Hardware Risk Management: Documenting Risk Before You Build
Most electronics failures were predictable. How to run a risk register from concept through production so field failures stop arriving as surprises.
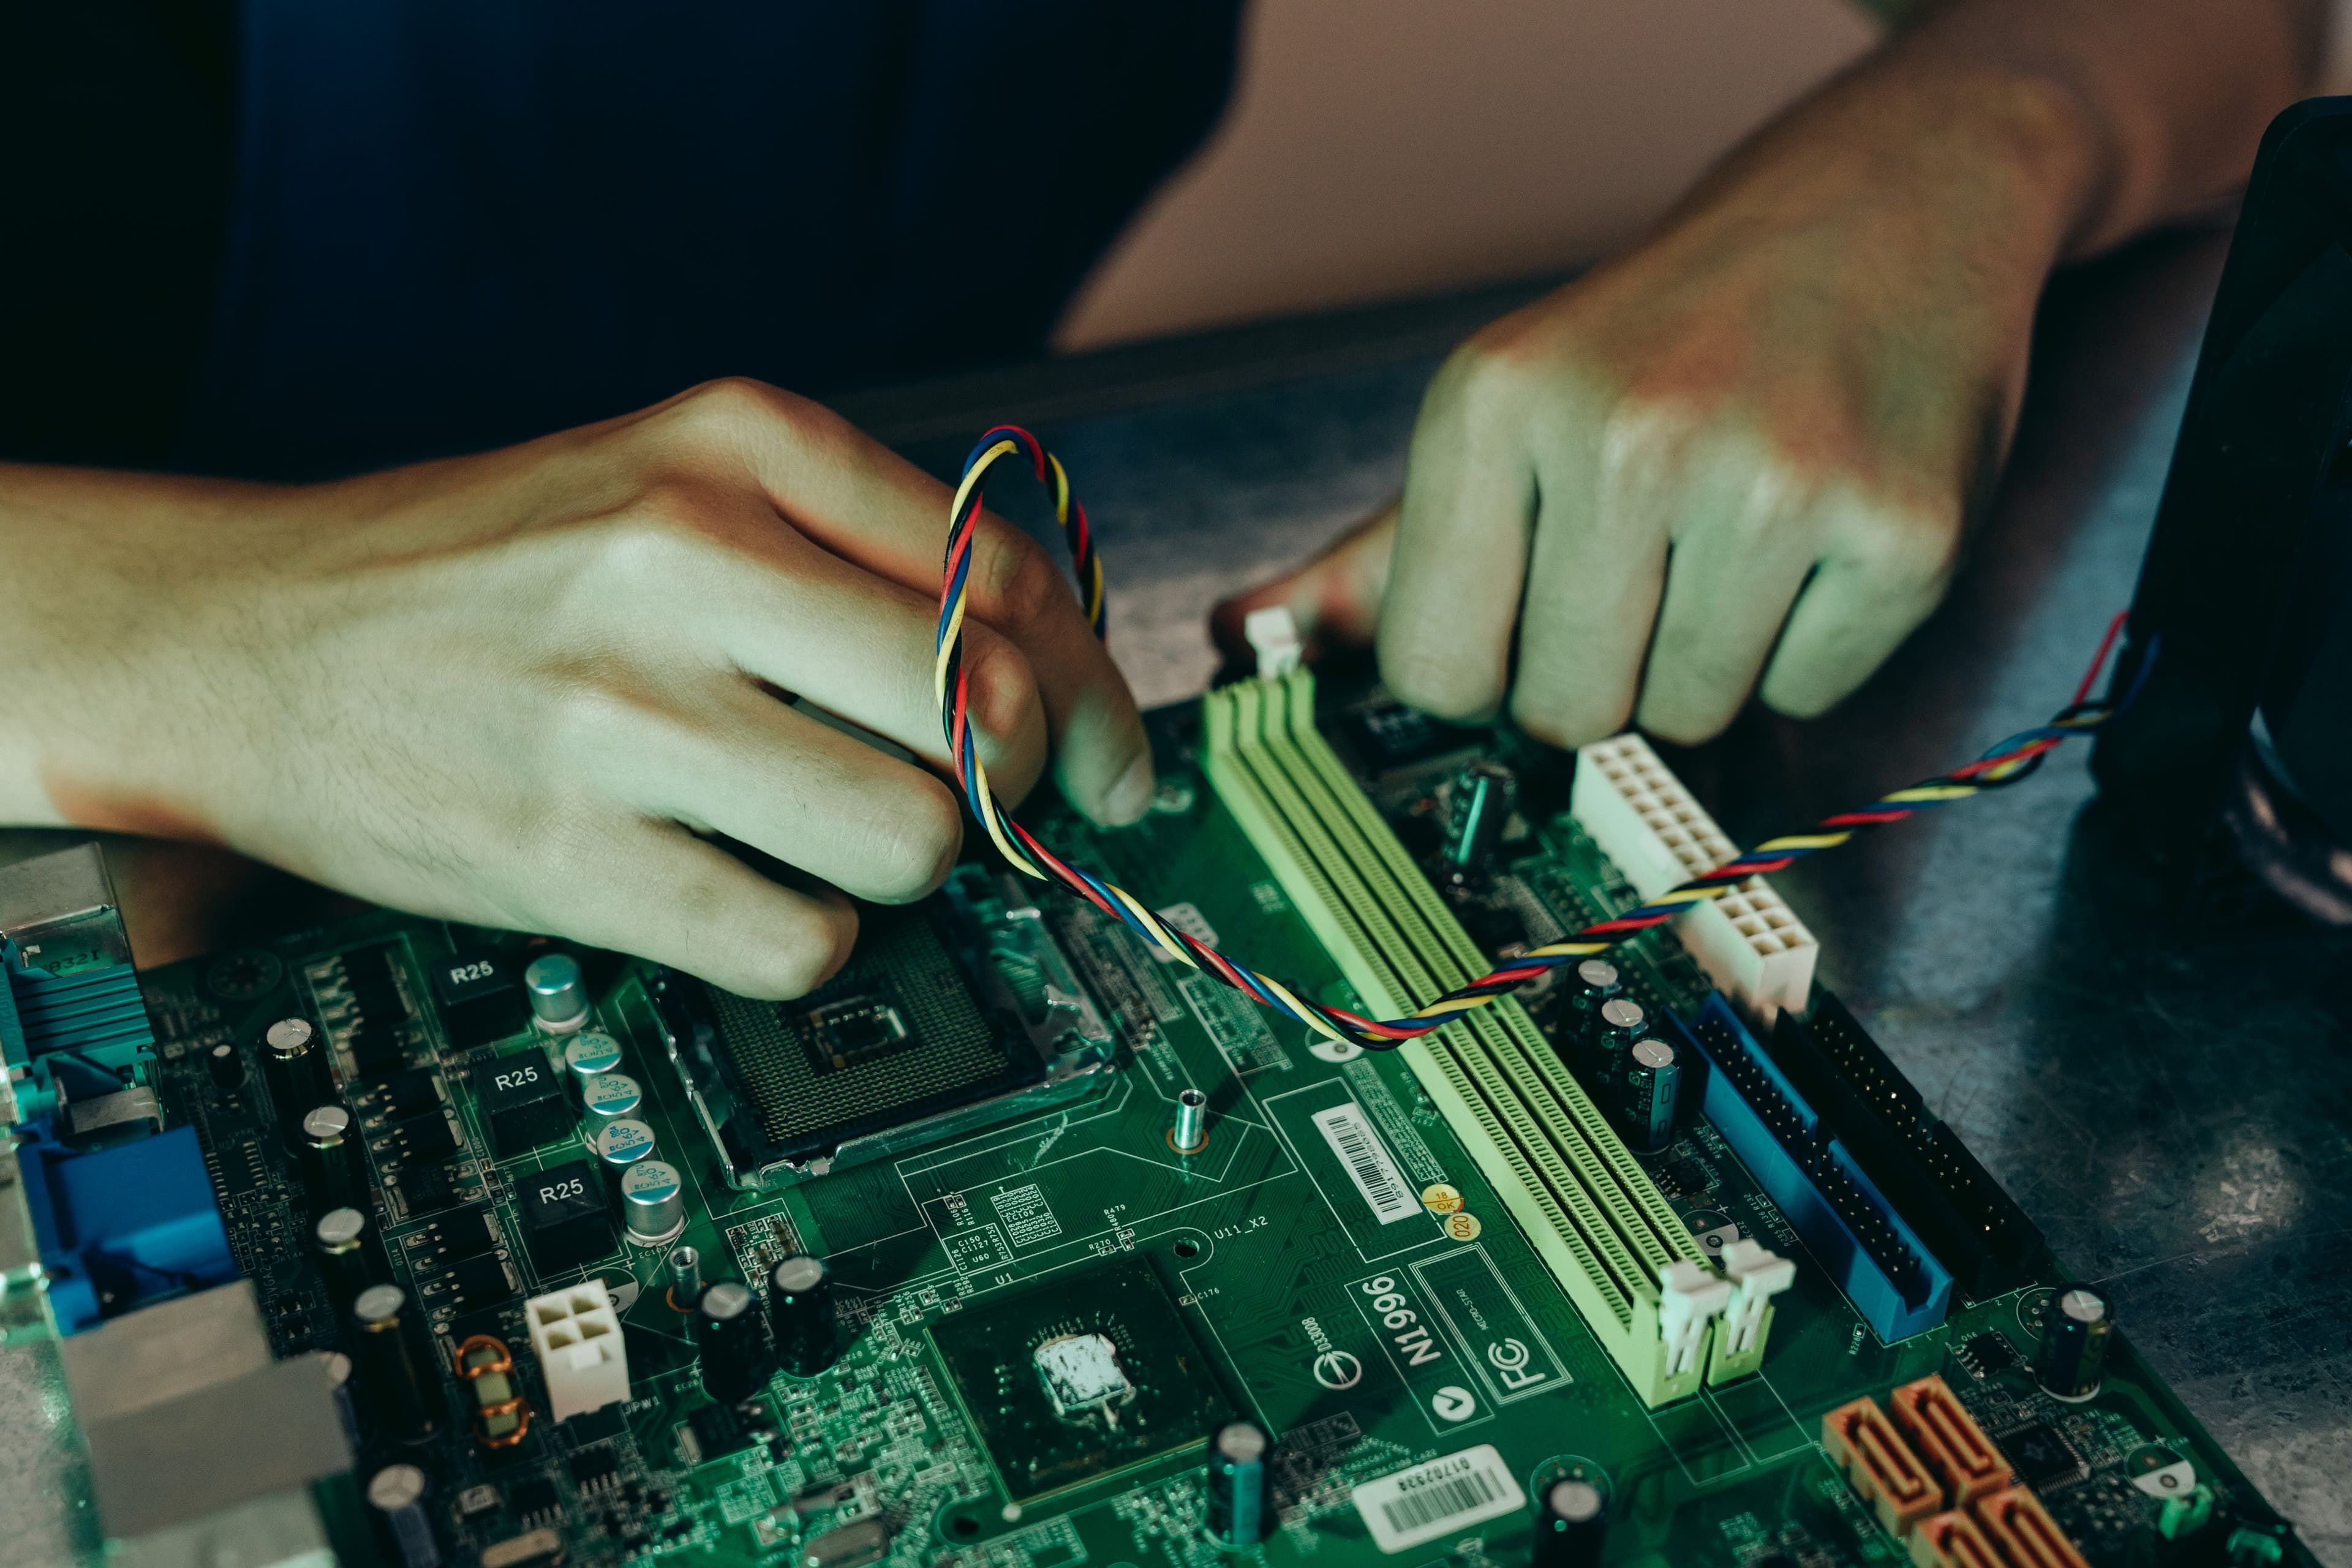
Hardware risk management is the practice of identifying, documenting and mitigating physical and design failure modes before a product is built. In electronics, that means writing down every known risk (a corrodible contact, an enclosure joint that can trap water, a component with a long lead time) at the point the feature is proposed, then carrying each risk into the test plan so it gets verified rather than discovered in the field.
The failures that hurt most were the ones somebody already suspected
Ask any hardware team about their worst field failure and you will usually hear a version of the same story. Someone raised a concern early. It was discussed verbally. It was not written down. The design moved on, the risk was never converted into a test case, and eighteen months later a batch came back from the field.
That is the entire problem. Hardware risk is rarely unknown. It is undocumented.
A small rusting element on a contact, a gasket seam that clogs with water, a connector that sits at the low point of the enclosure, a regulator running at 85 percent of its thermal envelope. Each of these is visible at design review. None of them fails on the bench. All of them fail in the field, at scale, and in ways that are expensive to recall.
At RND Square we treat risk documentation as a mandatory gate rather than an optional artifact. Every hardware idea, every feature, every design decision gets the same question attached to it: what is the risk in doing this? If there is a risk, it gets written down, discussed, and closed one of three ways. We proceed knowingly, we mitigate it in the design, or we do not proceed.
What actually belongs in a hardware risk entry
A risk register that just says "moisture ingress" is not a risk register. It is a worry list. A usable entry has five parts.
- The failure mode. What physically goes wrong. "Condensation forms on the underside of the PCB near the relay terminals during cold-start cycles."
- The trigger condition. What has to be true for it to happen. Temperature range, duty cycle, humidity, installation orientation, supply variation.
- The consequence and severity. Cosmetic, functional degradation, safety, total failure, regulatory exposure.
- The mitigation. Conformal coating, a drain path, a derated part, a firmware guard, or an explicit decision to accept the risk.
- The verification. The specific test that proves the mitigation works, and where that test lives. Design validation, production test, or field monitoring.
Point five is where most teams lose the thread. A risk that does not terminate in a test case is a risk you have documented and then forgotten. The whole value of writing it down is that it becomes an input to the test plan.
Risk shifts as the product moves through its lifecycle
The risks that matter at concept are not the risks that matter at scale.
Engineering stage risks are design risks. Thermal margin, signal integrity, tolerance stack-up on mechanical fits, component selection, certification exposure. These are cheap to fix and expensive to ignore.
Manufacturing stage risks are process and supply risks. Component end of life, single-source parts, a solder joint that is hard to inspect, an assembly step that depends on operator judgment, an alternate part nobody validated.
Operations stage risks are field risks. Corrosion, ingress, connector fatigue, firmware update failure, battery ageing, cellular coverage variation across regions.
A risk raised in engineering does not stop being a risk at handover. It has to travel. The reason a lot of hardware teams keep meeting the same failure twice is that risk lives in a design review deck that nobody opens again after the design is released.
Why spreadsheets stop working around the second variant
A risk register in a spreadsheet works for one product, one revision, one team, for about six months. Then the following happens.
Someone creates a copy for the new variant. The two copies diverge. A mitigation applied to variant A never reaches variant B. Nobody can tell which revision of the hardware a given risk applies to. The production team never sees the register at all, so the test that was supposed to catch the risk never gets added to the line. And when a unit comes back from the field, there is no way to connect the failure you are looking at to the risk somebody logged two years earlier.
Risk data is only useful when it is attached to the thing it describes. The board revision. The BOM line. The variant. The test case. The serial number.
How risk management works inside S3Suite
S3Suite treats risk as a first-class object in the Engineering Suite rather than a document.
- Risks are linked to project artifacts. A risk attaches to a schematic revision, a BOM line, a mechanical file or a firmware release, so it moves with the design instead of sitting beside it.
- Risks carry through to the test plan. A logged risk can be tied to a production checklist item or a Station Kiosk test step, so the mitigation is verified on every unit rather than assumed.
- Risks survive variants. When a variant is created, its inherited risks come with it, and variant-specific risks stay scoped to that variant.
- Risks connect to the field. When a unit comes back through RMA, the risk history for that revision is visible next to its test records and rework history, which is usually what turns a three-week root cause investigation into a one-hour one.
- BOM health scoring flags supply risk automatically. Components that are NRND, end of life, single sourced or long lead time surface as risk before procurement, not after.
The point is not the register. The point is that the risk, the mitigation and the proof are in one system, and the production team and the field team can both see them.
A practical way to start this week
You do not need a process rollout to begin. Take your current product and do three things.
Write down the ten failure modes your senior engineers already worry about. Not the theoretical ones. The ones that come up in conversation. For each one, name the test that would catch it, and check whether that test actually exists in your production flow or your validation plan. Then, for the ones with no test behind them, decide out loud whether you are mitigating or accepting.
Most teams find that between three and five of those ten have no verification behind them at all. That gap is your next quarter of field failures, and you have just found it for free.
FAQ
What is hardware risk management?
It is the process of identifying, documenting and mitigating potential failure modes in a physical product before it is built and shipped. Unlike software, hardware defects cannot be patched remotely, so the cost of a missed risk is a recall, a rework or a warranty claim rather than a hotfix.
When should risk assessment start in product development?
At concept, not at design review. The cheapest point to remove a risk is before the architecture is fixed. Every stage after that increases the cost of change, which is why a risk found at production release usually gets accepted rather than fixed.
What is the difference between a risk register and an FMEA?
An FMEA is a structured, scored analysis usually applied to a specific design or process. A risk register is broader and continuous, covering design, supply, manufacturing and field risks across the product lifecycle. Most hardware teams need the register first and the FMEA where severity justifies it.
How does a PLM help with hardware risk management?
A PLM links each risk to the specific revision, variant, BOM line and test case it relates to, so mitigations are verified in production and risk history is available when a field failure is investigated. That linkage is what a spreadsheet cannot do.
Should manufacturing see the engineering risk register?
Yes, at least the portion that terminates in a production test. If the production team does not know why a test step exists, it becomes the first step skipped when the line is under pressure.
CTA: Documenting risk properly takes a system, not a spreadsheet. See how the S3Suite Engineering Suite links risks to revisions, variants and production test steps. [Get a demo]
Internal links: /s3suite (Engineering Suite), /insights/electronics-production-test-sequence, /insights/bom-health-score-how-it-is-calculated, /insights/how-to-find-component-end-of-life